Catches data problems before anyone notices them.
The challenge
Data problems were usually discovered late, when a report looked wrong or a customer noticed. Nobody had a reliable daily view of what was broken and who should fix it.
Our approach
We built a daily anomaly engine: a catalogue of read-only checks, each tied to a real past incident, with state tracking, alerts and an AI-written summary.
Everyday impact
The team starts each day knowing exactly what needs fixing, and who owns it.
What we built
Each check has a severity, an owner, fix steps and the past incident it is designed to catch.
Every run folds results into state, so the team sees what’s new today versus what’s still open.
AI writes a daily summary from the computed facts, not from guesses.
Checks run in read-only transactions with timeouts, and any SQL containing write keywords is rejected.
Production checks run on the database scheduler and alert via team chat and email, with a heartbeat monitor.
How it works
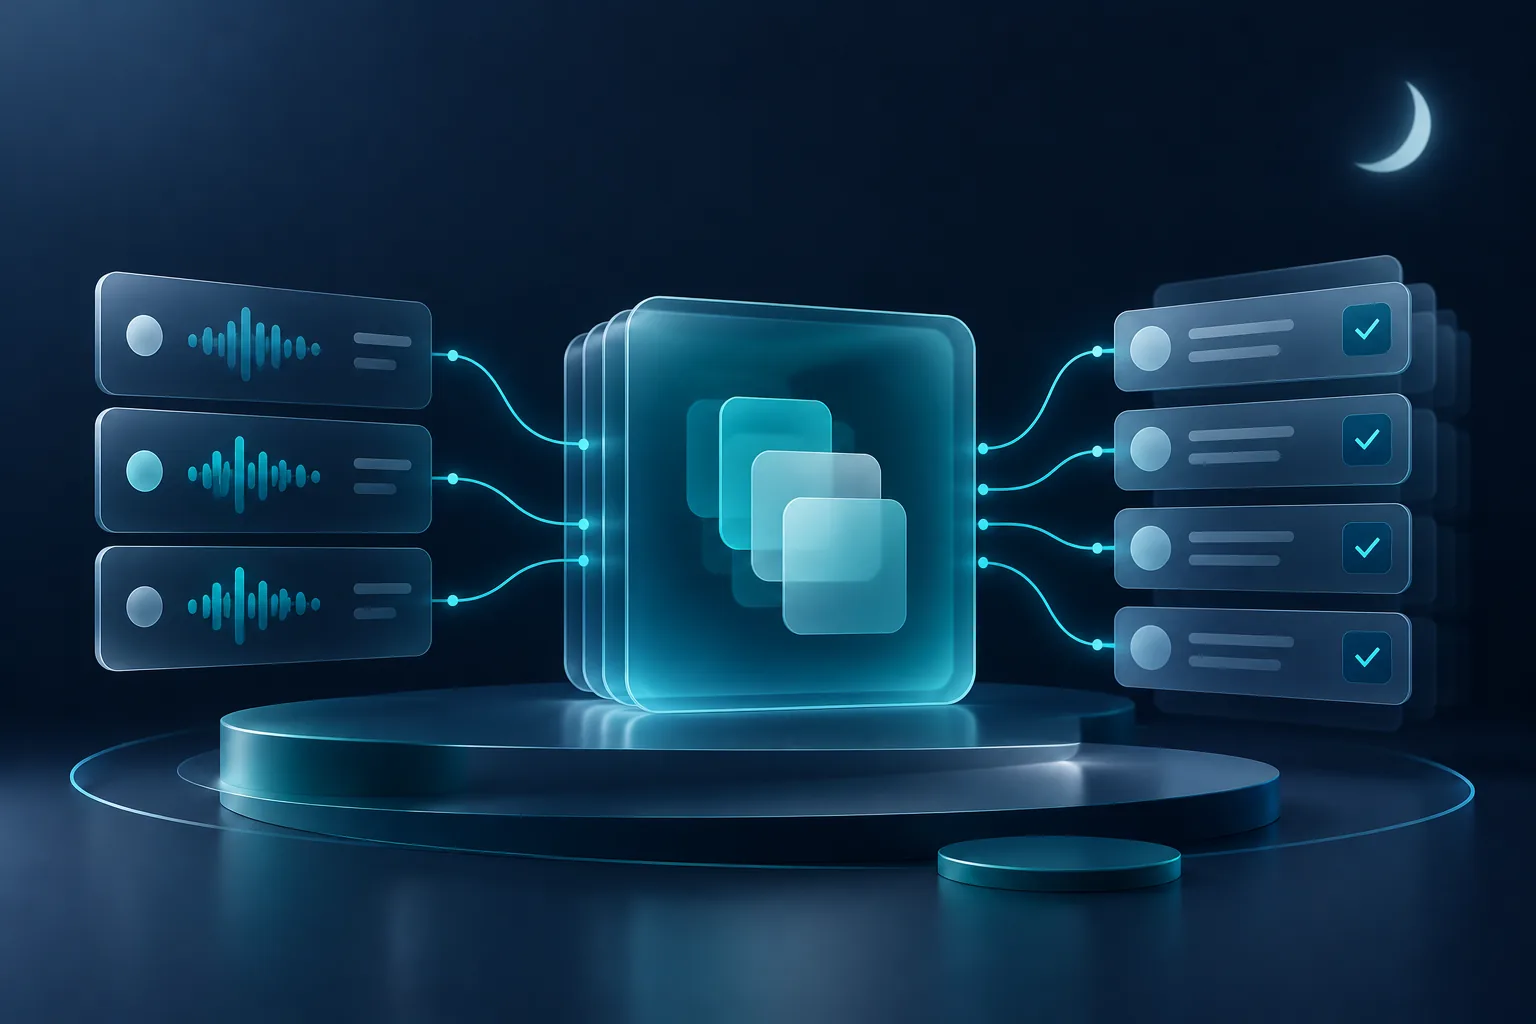
Every morning the scheduler runs the full check catalogue.
Results are compared with yesterday to find new, ongoing and solved issues.
AI writes a short summary, and alerts go to chat and email.
Each issue arrives with an owner and fix steps.
More work
Start a conversation
Tell us what you’re trying to build. We’ll talk through how we’d approach it and what a sensible first step looks like.