One command centre for every AI agent, conversation and dollar spent.
The challenge
AI agents were talking to customers across chat, voice and SMS, but nobody had one place to see what they were doing, what they cost, or when a human needed to step in. Proactive outreach needed strict rules so automation never overstepped.
Our approach
We built an operations console that sits over every AI channel: scheduled jobs, human-reviewed outreach, conversation analysis, knowledge bases, cost tracking and an evaluation harness. Guardrails are enforced in code, not just policy.
Everyday impact
The team sees what every AI agent is doing, what it costs and when it needs a human, without digging through logs.
What we built
Every job is a configurable row with on/off switches, run history and a “run now” button, dispatched every minute by a database scheduler.
Rules queue reminders, an AI writer drafts personalised messages from live context, and only explicitly allow-listed rules send automatically. Everything else waits in an editable review queue.
Quiet hours, daily and weekly caps, snooze, do-not-disturb, consent and escalation checks run before any message goes out, with an atomic claim so nothing sends twice.
A funnel from sent to replied to completed shows whether outreach actually helps, per rule and per person.
AI scores conversations across five channels, logs issues, groups them into categories and writes an executive summary.
A streaming, tool-calling assistant answers questions about spend, tokens, model performance, job status and problem conversations, with read-only database access.
Create agents, assign tools, edit memory modules and test against production. Knowledge bases get embeddings, summaries, duplicate detection and document import.
Every AI call is logged with tokens and cost from one rate card. An evaluation harness checks AI messages against hard rules and an AI judge, with gate tests in CI.
How it works
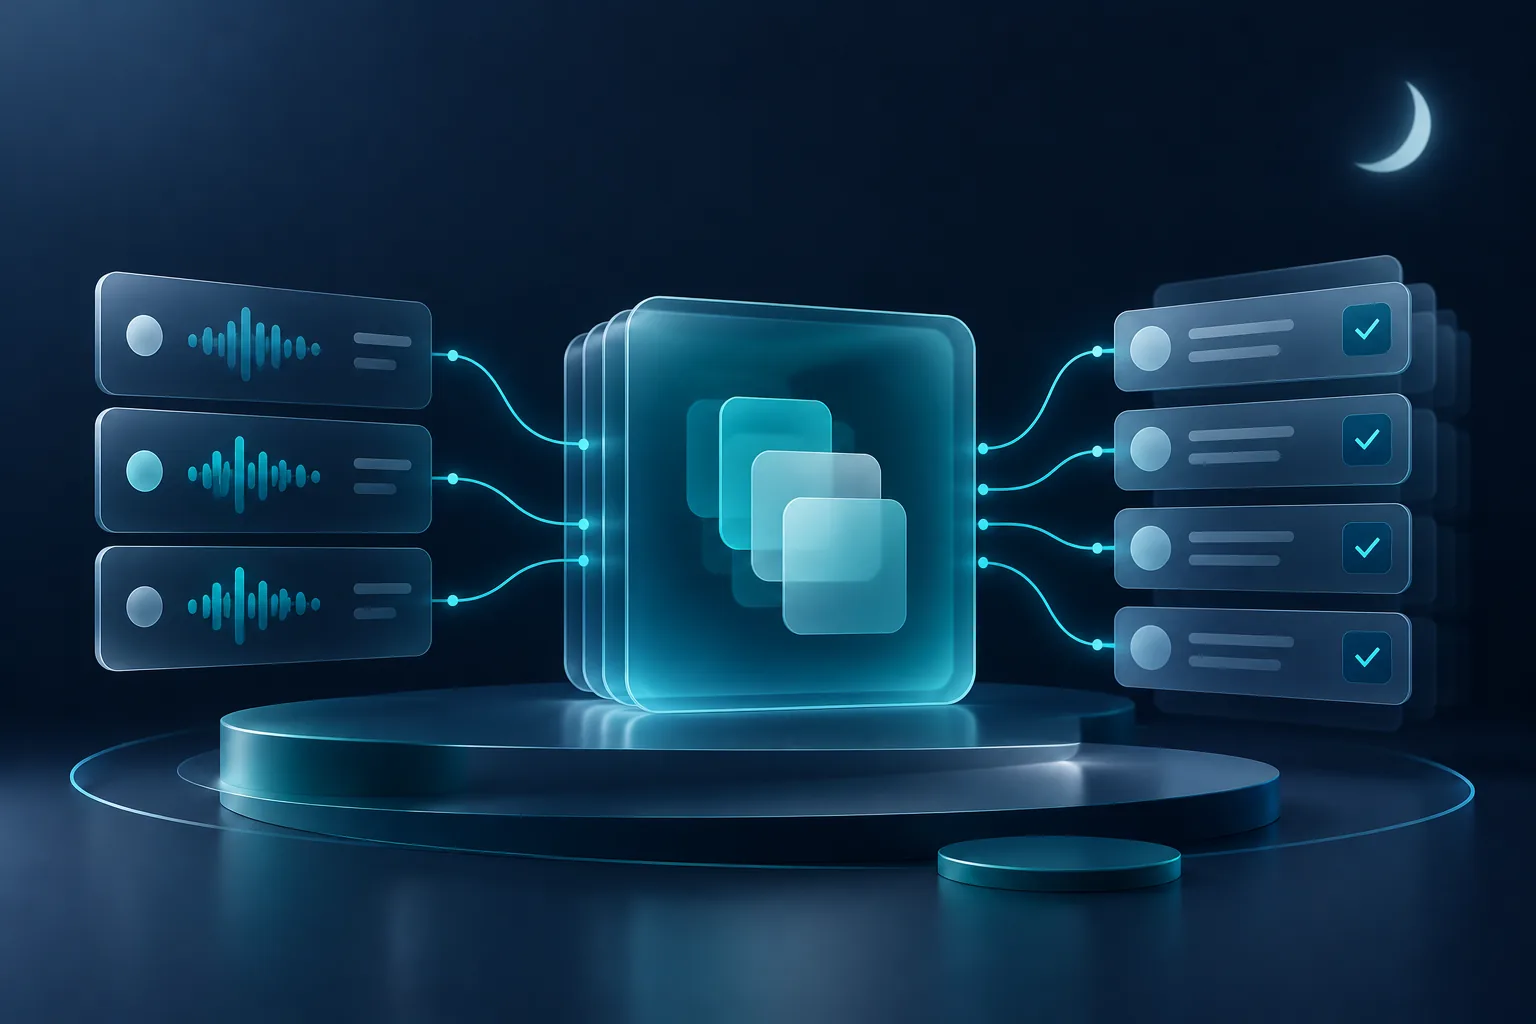
A scheduler triggers jobs every minute: scans, reminders, analysis and reports.
AI drafts outreach or analysis, then hard gates check consent, timing and caps.
Allow-listed messages send. Everything else lands in a human review queue.
Results, costs and outcomes flow back into dashboards and evaluations.
More work
Start a conversation
Tell us what you’re trying to build. We’ll talk through how we’d approach it and what a sensible first step looks like.